2000 words sampled at random from the 50,000 most frequent word types of a
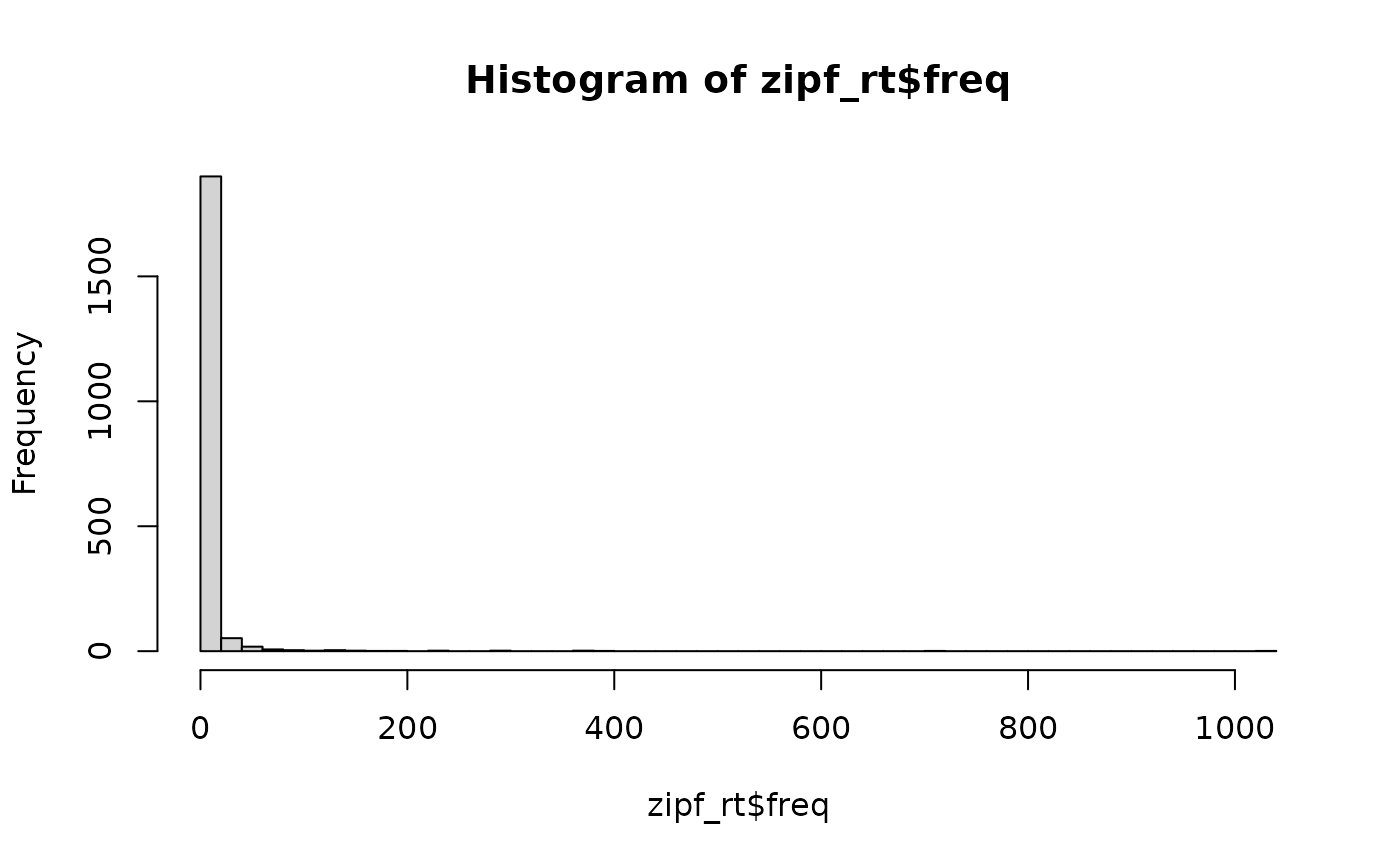
corpus whose frequencies follow Zipf's law (frequency proportional to
1 / rank). As in real corpora, most words are rare and a few are very
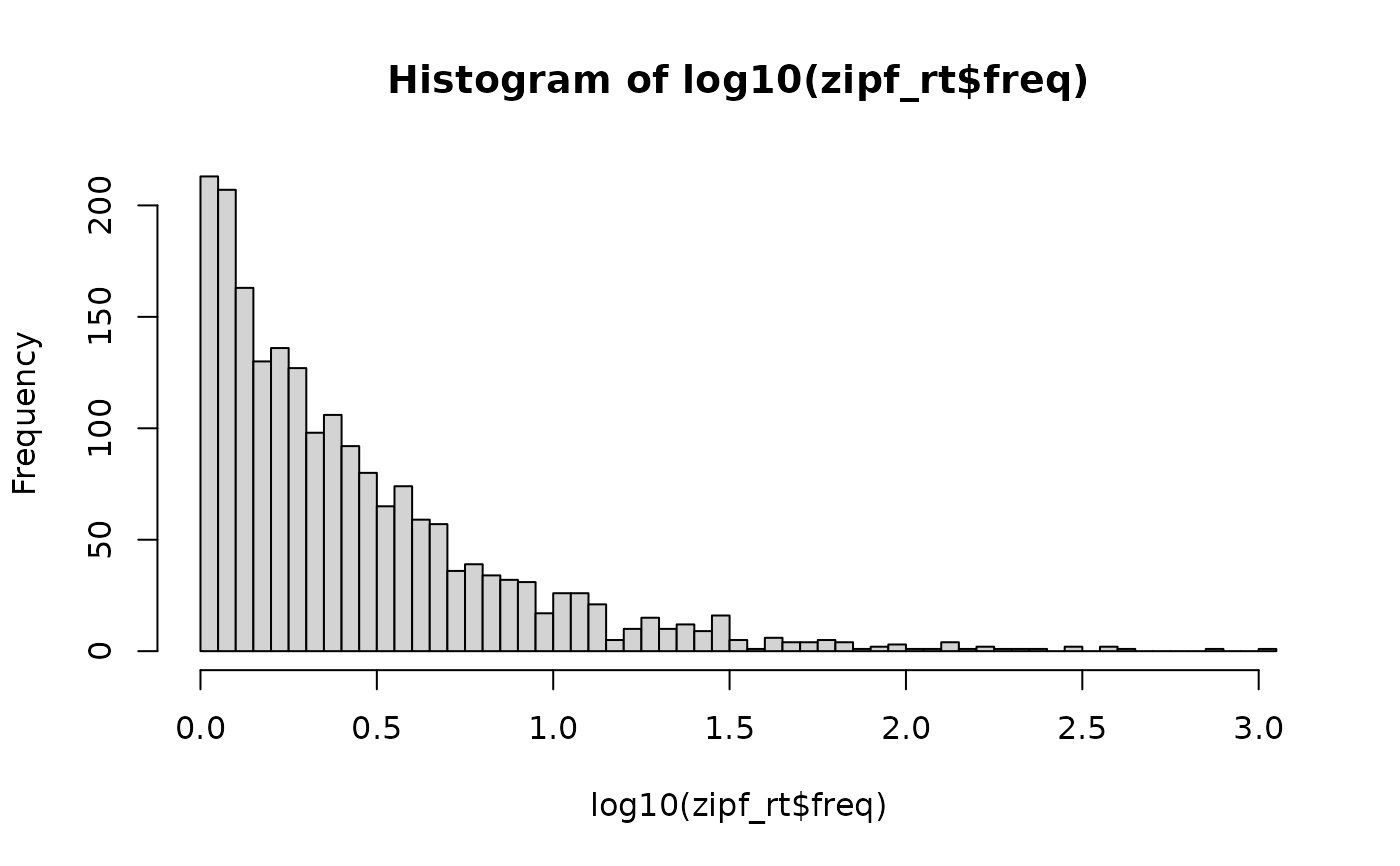
frequent, so frequency is extremely skewed. For log transformations.
A tibble with 2000 rows and 4 columns:
- word
Word ID, w0001 to w2000.
- rank
Frequency rank in the corpus, 1 to 50,000.
- freq
Frequency per million words, 50000 / rank.
- rt
Reaction time in ms.
Source
data-raw/zipf_rt.R
Details
True model: log(rt) = 6.62 - 0.08 * log10(freq) + e, with
e normal, SD 0.15.
Examples
hist(zipf_rt$freq, breaks = 50)
 hist(log10(zipf_rt$freq), breaks = 50)
 coef(lm(log(rt) ~ log10(freq), data = zipf_rt))
#> (Intercept) log10(freq)
#> 6.62591038 -0.09607583
