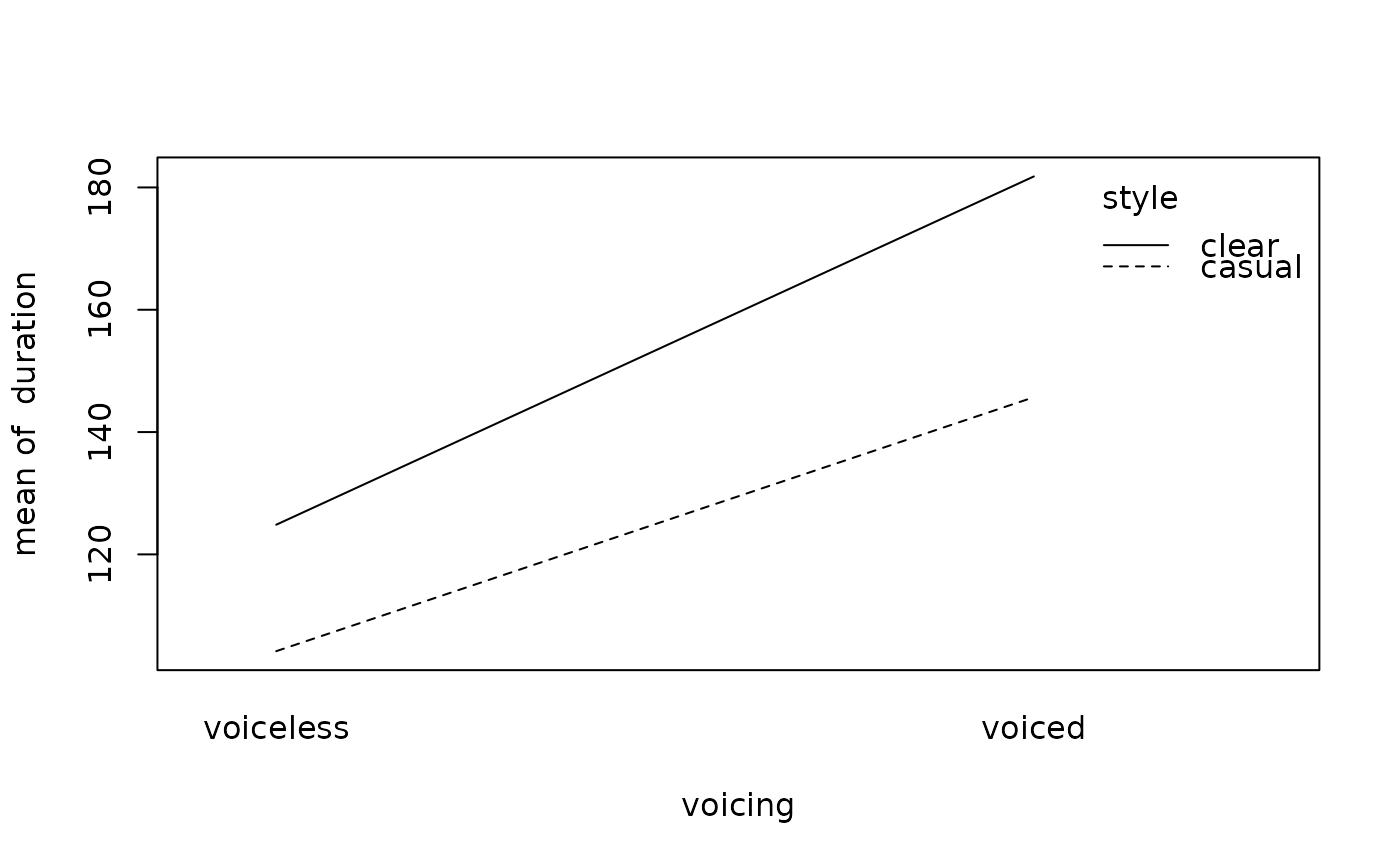
A 2 x 2 design: casual or clear speech, voiceless or voiced following consonant, 40 tokens per cell. The voicing effect is larger in clear speech, which makes this a categorical-by-categorical interaction.
Format
A tibble with 160 rows and 3 columns:
- style
"casual"or"clear".- voicing
"voiceless"or"voiced".- duration
Vowel duration in ms.
Details
True model: cell means are 110 (casual, voiceless), 145 (casual, voiced), 125 (clear, voiceless) and 180 ms (clear, voiced); SD 18 ms.
Examples
m <- lm(duration ~ style * voicing, data = style_voicing)
coef(m)
#>              (Intercept)               styleclear            voicingvoiced
#>                  104.175                   20.675                   41.525
#> styleclear:voicingvoiced
#>                   15.425
with(style_voicing, interaction.plot(voicing, style, duration))